
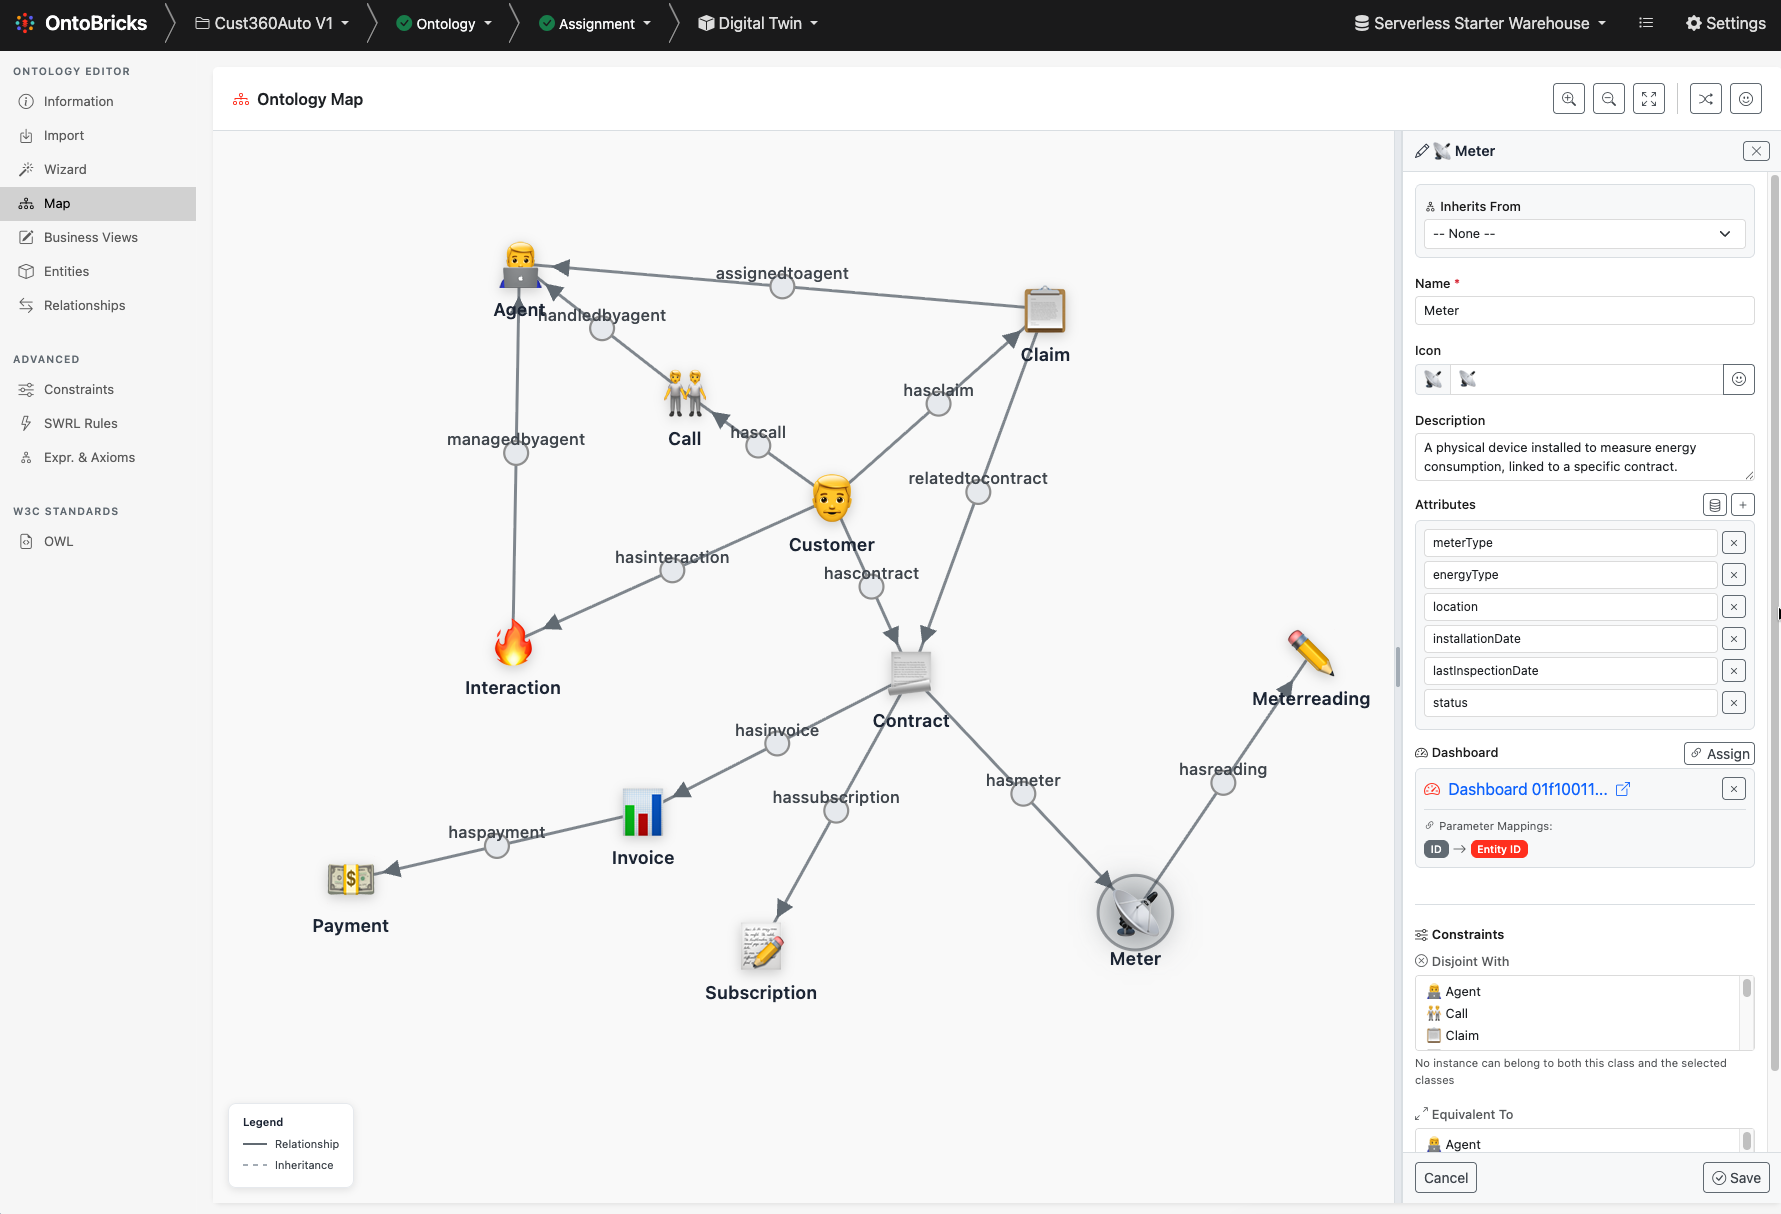
Visual ontology design
Drag-and-drop entities, relationships, and class hierarchies in Ontology Studio. Or import FIBO, CDISC, IOF and other OWL/RDFS standards.
OntoBricks designs ontologies, maps them to Unity Catalog tables, materializes or virtualizes triples into a triple store, reasons over the graph, and serves it to your apps and AI agents — the full pipeline in four clicks.
Ontologies in OWL — visually or LLM-generated
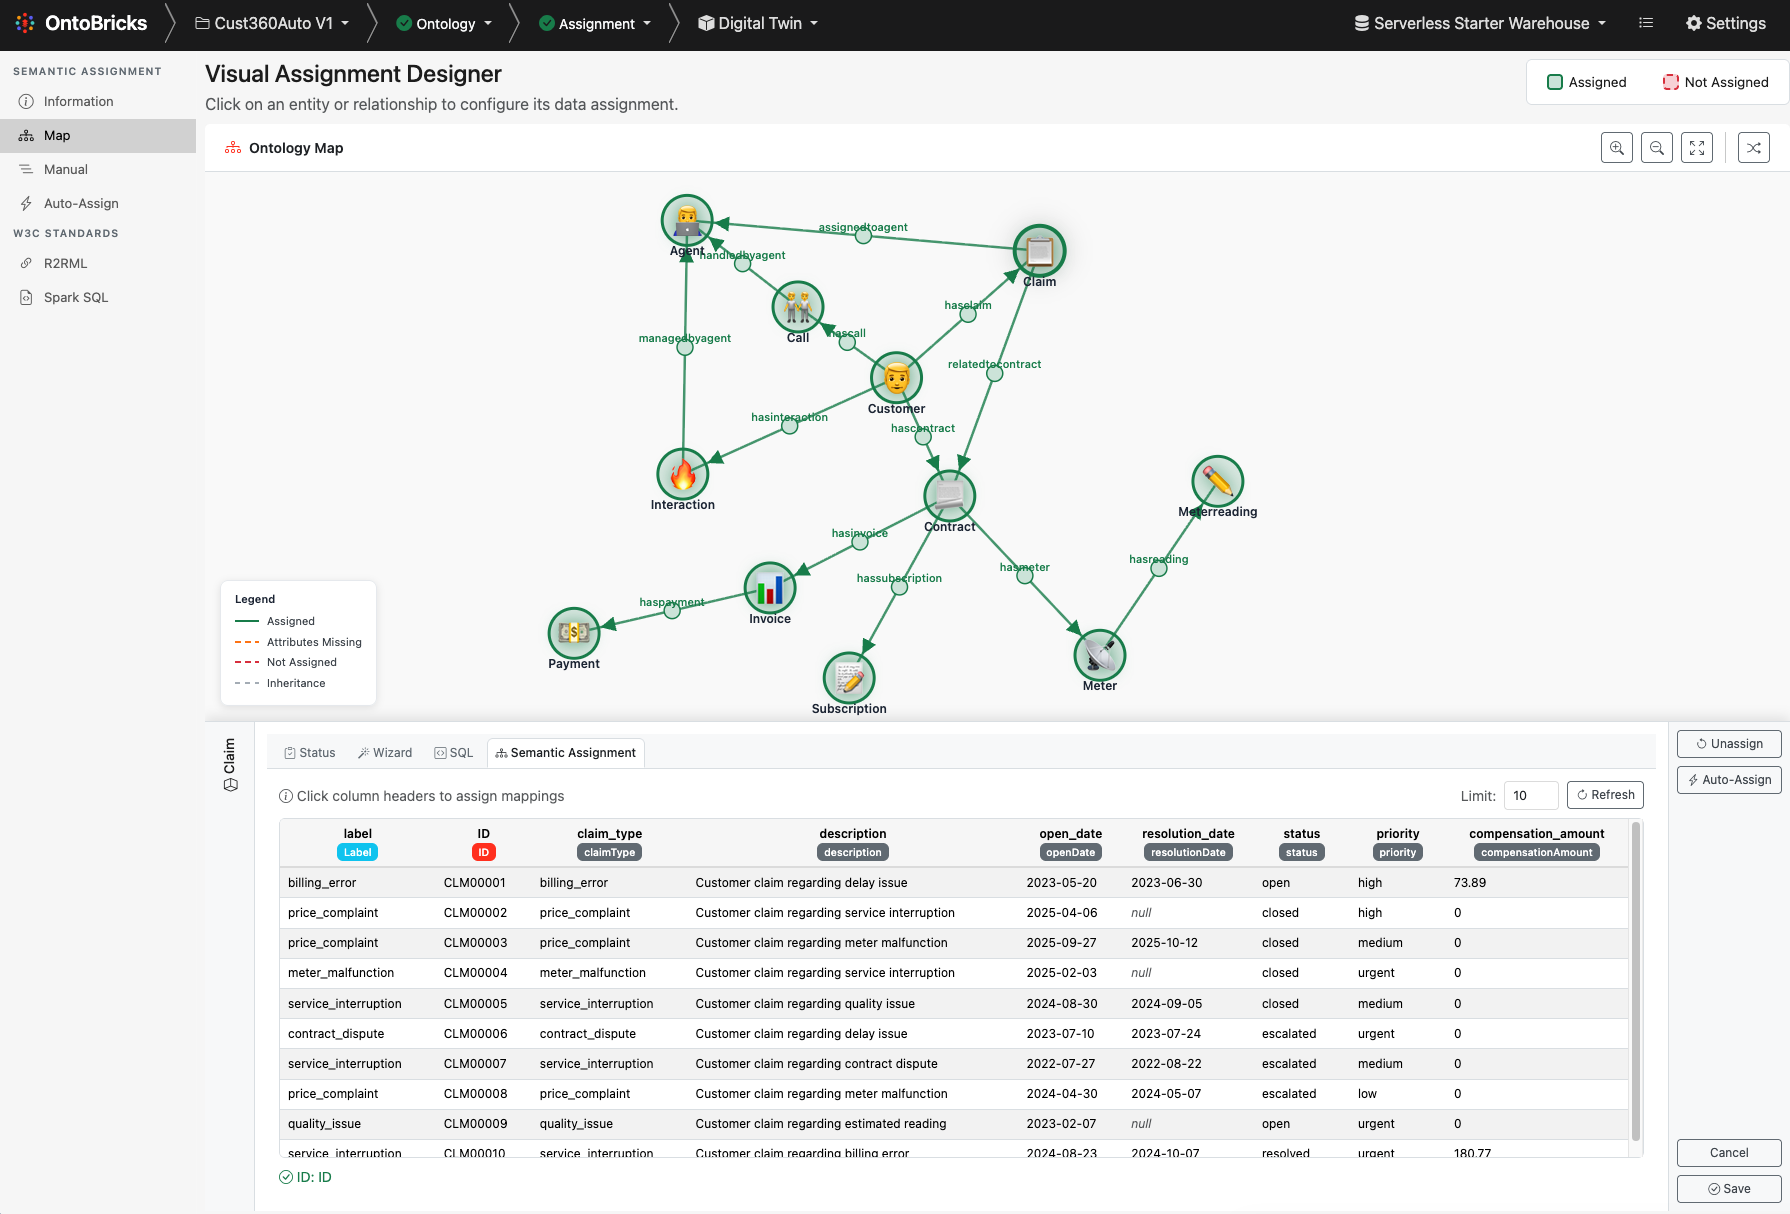
Entities to Unity Catalog tables via R2RML
OWL 2 RL, SWRL rules & SHACL checks
GraphQL API & MCP for AI agents
OntoBricks brings ontologies, reasoning, and graph exploration to the Lakehouse — without leaving Unity Catalog or writing a single triple by hand.
Drag-and-drop entities, relationships, and class hierarchies in Ontology Studio. Or import FIBO, CDISC, IOF and other OWL/RDFS standards.
An LLM wizard writes the SQL that binds ontology entities to your tables, column by column — then auto-maps everything else in a single batch.
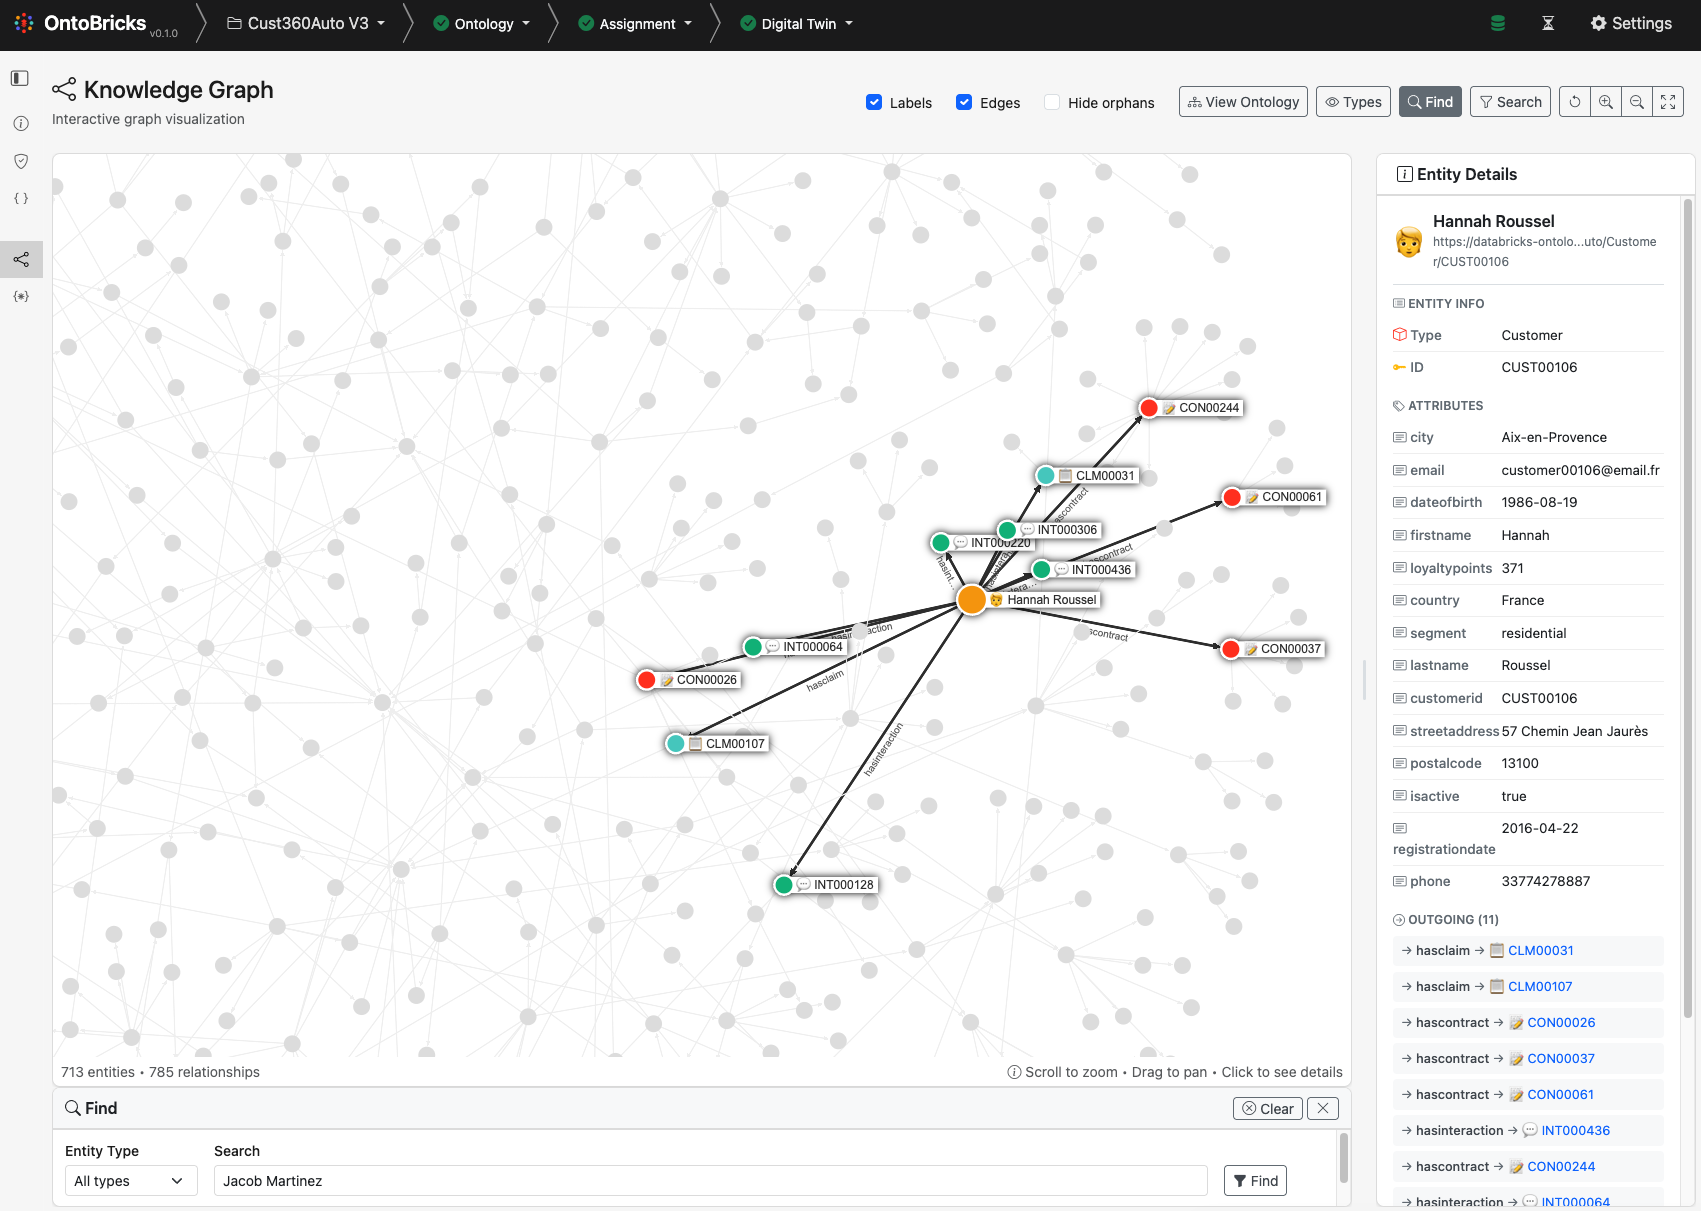
Materialize triples into the backend you choose — Lakebase (Postgres), Lakehouse (Delta) or Neo4j — incremental by default and no manual SQL, or keep them virtual with a live pass-through view over the Lakehouse.
Run OWL 2 RL deductive closure, SWRL business rules, transitive/symmetric expansion, and W3C SHACL data-quality validation over the graph.
A GraphQL schema is generated from your ontology at runtime — traverse nested relationships in a GraphiQL playground, per project.
Expose the knowledge graph to LLM agents through the Model Context Protocol — connect from Cursor, Claude Desktop, or the Databricks Playground.
LLM-powered automation handles the heavy lifting — you stay in control at every step.
Fetch table and column metadata straight from Unity Catalog. OntoBricks reads your schema so it understands what it's modeling.
A three-stage wizard detects entities from Data Assets and the Knowledge Store, you review the catalog, then relations and axioms merge in — append-only.
Generate R2RML mappings for every entity and relationship, with multi-pass column matching and partial-mapping detection.
Materialize triples into the store, then query with GraphQL or SPARQL, or explore the interactive, WebGL-powered knowledge graph.
Walkthroughs, release highlights, and deep dives. View the full playlist ↗
# Clone the repository
git clone https://github.com/databrickslabs/ontobricks
cd ontobricks

# Install dependencies with uv
uv sync --frozen --extra lakebase

# Configure your Databricks credentials
cp .env.example .env
# edit .env → host, token, SQL warehouse ID

# Start the app → http://localhost:8000
scripts/start.sh# Authenticate against your workspace
databricks auth login --host https://<workspace>
# Deploy as a native Databricks App
make deploy
# Then bind the sql-warehouse & volume resources
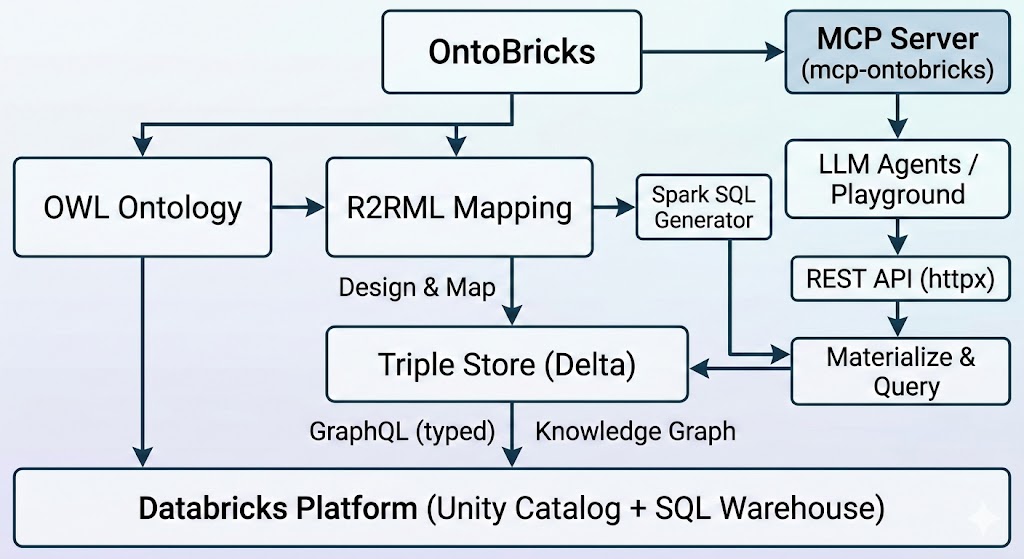
# in Compute → Apps → ontobricks → ResourcesOntoBricks stitches together semantic-web standards, graph databases, and formal reasoning on top of the Databricks Platform. Ontologies compile to R2RML, mappings become Spark SQL, and triples land in Lakebase, Delta or Neo4j — all governed by Unity Catalog.
OntoBricks is source-available under the Databricks License and welcomes contributions. See everyone on GitHub ↗
Released October 2026 — Lakehouse//RT reads, a staged Generate wizard, and a faster Explorer. Read the full release notes ↗
Point Knowledge Graph reads at a serverless Lakehouse//RT warehouse over the Statement Execution API. Builds stay on a classic or serverless warehouse that still accepts DDL.
Detect entities, review and lock the catalog, then complete relations, attributes, and axioms with checkpoints. The merge appends to the existing ontology instead of replacing it.
Parsed documents live in Lakebase Postgres — not a Unity Catalog Volume. Generate and Mapping share the same corpus; no READ VOLUME grant is required.
Each instance can push domain configuration (OWL, R2RML, SHACL, layouts, rules) to one GitHub repository. Lakebase stays the source of truth; Load from GitHub restores domains through OBX import.
Run SPARQL against the graph and inspect the generated SQL. Graph status no longer blocks first paint; adjacency indexes, paged BFS, and a canvas stopwatch cut preview and expansion time.
Designer is now Studio. Bind Databricks Jobs as class actions, run SWRL on one entity, and check a node against inherited SHACL shapes — from Explorer or MCP.
Source-available, Databricks-native, and yours to explore.